The Scientist Pattern
(Originally drafted in October 2023 during my tenure at Xero. Republished here in October 2026 with updated context and removed proprietary references)
“In short, a proxy is a wrapper or agent object that is being called by the client to access the real serving object behind the scenes.” — Proxy pattern, Wikipedia
Consider a scenario familiar to anyone maintaining a large monolithic API: you’re refactoring endpoints towards a new architecture, and it’s going well – until it isn’t. An API contract gets inadvertently changed, data gets lost, and customers notice before you do.
Once the dust settles, the question becomes: how do we make sure this never happens again?
One option is to diff every JSON response by hand using something like KDiff. That works, technically, but it’s incredibly time-consuming - especially for endpoints with lots of conditional branches, where you’d need to exercise every path with realistic data just to compare outputs.
Another option is JSON Schema validation: assert that the JSON returned from the refactored API matches the shape we expect. But this only covers reads.
What about writes? Not every POST or PUT endpoint returns the data you sent – plenty just return an HTTP 200 – so relying on the response alone isn’t enough to prove the write behaved identically.
Which raises the bigger question: could we compare the behaviour of the legacy code versus the refactored code automatically, on live traffic, without affecting customers?
The Scientist Pattern
The Scientist pattern - originally released as a Ruby library by GitHub - introduces the concept of ’experiments’ as a way of comparing refactored and legacy code path behaviour. It works roughly like this:
- A caller invokes a method
- The method has two code paths: legacy and refactored
- Scientist randomly selects a code path to invoke
- The selected code path is invoked and returns a response
- The other code path is also invoked and returns a response
- Both responses are compared, and the initial path’s response is returned to the caller
- Execution duration and any differences are published to a log
- The response from the initially selected path is returned
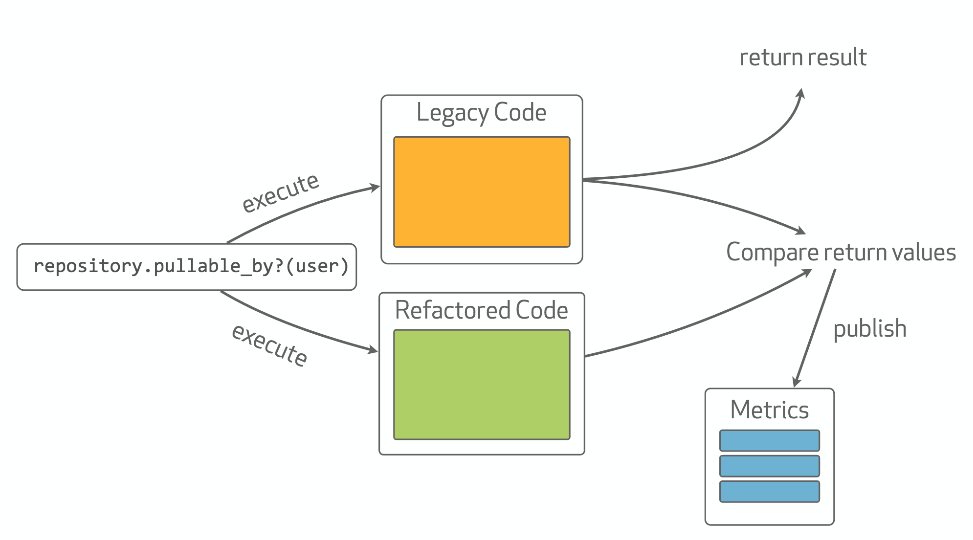
This library has a .NET port, and it’s a genuinely elegant idea: run both paths, diff the results in the background, and let real production traffic tell you whether your refactor is behaviourally identical before you commit to it.
Forming some requirements for using it against a large .NET Framework API:
- Scientist functionality needs to be non-invasive - minimal changes to legacy code paths
- It must be easy to remove once refactoring of a code path is complete
- Because Scientist randomises the order in which the legacy (
Use) and refactored (Try) blocks run, either path might execute first - JSON results returned to clients must be comparable so discrepancies can be identified
But there’s a catch: Scientist invokes two code paths, which means double the compute per request.
For reads, that extra load might be tolerable. But APIs like this tend to lean heavily on internal services – and two code paths means twice the load on every downstream service involved in the request. Worse, for writes it opens up the possibility of sending the same values twice. Create an invoice through both paths, and congratulations: you’ve created two identical invoices.
Maybe we could cache and re-use the service result for read code paths, and prevent the second invocation from proceeding on write code paths?
The Proxy Pattern
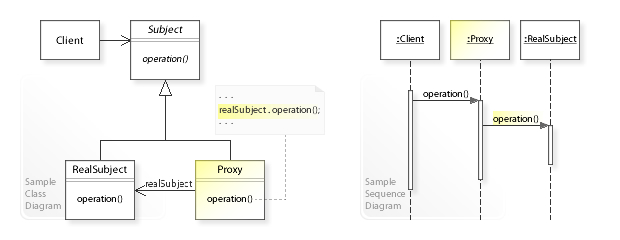
One of the Gang of Four design patterns, the Proxy pattern ‘wraps’ an object instance with another to provide additional functionality. The proxy implements the same interface as the real subject, so client invocations go via the proxy before being forwarded on:
public interface ISubject
{
    void Operation();
}

public class RealSubject : ISubject
{
    public void Operation()
    {
        // Do something here...
    }
}

public class Proxy : ISubject
{
    private RealSubject _realSubject;

    public void Operation()
    {
        Console.WriteLine("Do something else before...");

        _realSubject.Operation();
    }
}
This classic example relies on the proxy being declared up front. The interesting question is: could we achieve this at runtime, without modifying the original implementation?
Interception in .NET
The Castle.DynamicProxy library - part of the Castle Project since 2011, and used under the hood by several mocking frameworks - allows dynamic creation of object instances that match a particular interface at runtime:
var proxy = generator.CreateInterfaceProxyWithoutTarget(typeof(TInterface), ...);It also exposes an IInterceptor interface with a single method:
public interface IInterceptor
{
    void Intercept(IInvocation invocation);
}
The IInvocation object carries everything about the call - arguments, the MethodInfo, the target, and the return value - plus a Proceed() method to forward the invocation.
Under the aspect-oriented programming paradigm (ironically, a more recent addition to C# itself), these are known as ‘interceptors’. A trivial example that logs method arguments:
public class MethodArgumentLogger : IInterceptor
{
    public void Intercept(IInvocation invocation)
    {
        foreach (object argument in invocation.Arguments)
        {
            _logger.Debug(argument.ToString());
        }

        invocation.Proceed();
    }
}
This is a powerful approach: functionality on existing object instances can be extended without modifying their implementations – at runtime. From the client’s perspective nothing has changed: the object is wrapped in a proxy with the same method signatures and return types as the target.
Related tools worth knowing about: Pex and Moles (from Microsoft Research, later rebranded as Microsoft Fakes) and TypeMock Isolator tackle a similar problem – testing compiled code that can’t easily be changed – at the Intermediate Language level. All are worth mentioning because they target maintaining legacy systems, just with a different mechanism.
Applying it to WCF service calls
Imagine an API where controllers consume internal WCF services through a ChannelFactory abstraction injected via a DI container, resolved like this:
using (var channel = _channelFactory.CreateProxy())
{
    DataContract contract = channel.Channel.CreateOrganisation();
    ...
}
Because everything flows through the DI container, we can rebind the ChannelFactory interface to a custom provider:
private void RebindProxyChannelFactory(IKernel kernel)
{
    kernel.Rebind(typeof(IProxyChannelFactory<>))
        .ToGenericProvider(typeof(ProxyChannelFactoryProviderScientist<>))
        .InSingletonScope();
}
The custom provider creates a ProxyChannelFactoryScientist<T> that, instead of handing back a plain Channel, wraps it in a Castle.DynamicProxy with a WcfMethodInterceptor:
private T CreateChannelProxy(bool compareWrites)
{
    var target = _proxyGenerator.CreateInterfaceProxyWithoutTarget(
        typeof(T),
        new[] { typeof(ICommunicationObject) },
        ProxyGenerationOptions.Default,
        new WcfMethodInterceptor<T>(_createChannelCallback,
            _wcfMethodResultCache, _methodArgumentComparer, compareWrites));

    return target as T;
}
Scientist for reads
The requirement for the interceptor is simple: cache the return value on the first invocation, and return the same value for the second. Since the same method on the same service might be called anywhere, we need a cache keyed by method name and arguments.
A MethodResultCache backed by a generic Dictionary<K, V> gives us Add, Remove, Has and Get for wrapped results (MethodResultCacheItem stores the class name, method name, original arguments, and result, overriding ToString() for debuggability):
public void Intercept(IInvocation invocation)
{
    var returnValue = _methodResultCache.Has(invocation) ?
        ReturnCachedValue(invocation) : InvokeChannelMethod(invocation);

    invocation.ReturnValue = returnValue;
}
On a cache hit, ReturnCachedValue() retrieves the stored value, removes it from the cache, and returns it - so the second code path gets the result from the first, and the underlying Channel is only ever invoked once.
Invoking the real method means reflection, careful unwrapping of TargetInvocationException, and - importantly - preserving whatever channel disposal semantics the original implementation had:
private object InvokeChannelMethod(IInvocation invocation)
{
    object returnValue;

    var channel = _createChannelCallback();

    try
    {
        returnValue = invocation.Method.Invoke(channel, invocation.Arguments);

        if (returnValue != null)
        {
            _methodResultCache.Add(invocation, returnValue);
        }
    }
    catch (TargetInvocationException ex)
    {
        if (ex.InnerException != null)
        {
            throw ex.InnerException;
        }

        throw;
    }
    finally
    {
        (channel as ICommunicationObject).CloseConnection();
    }

    return returnValue;
}
Scientist for writes
For writes, the interceptor instead compares the arguments of both invocations – they should be identical if the refactor hasn’t changed behaviour.
Hand-writing comparison logic for arbitrary object graphs would be painful, but the CompareNETObjects NuGet library performs deep comparison of two object instances, collections included:
public class MethodArgumentComparer : IMethodArgumentComparer
{
    public bool AreArgumentsEqual(object[] firstMethodArguments,
        object[] secondMethodArguments)
    {
        CompareLogic compareLogic = new CompareLogic();

        var result = compareLogic.Compare(firstMethodArguments,
            secondMethodArguments);

        return result.AreEqual;
    }
}
By virtue of checking the cache before invoking the underlying Channel, Intercept() also prevents doubling-up on writes – the second path’s arguments are compared against the cached first invocation, and a mismatch throws (or logs):
private object ReturnCachedValue(IInvocation invocation)
{
    MethodResultCacheItem cacheItem = _methodResultCache.Get(invocation);
    var returnValue = cacheItem.Result;
    _methodResultCache.Remove(invocation);

    if (_compareWrites)
    {
        bool isIdentical =
            _methodArgumentComparer.AreArgumentsEqual(
                invocation.Arguments, cacheItem.Arguments);

        if (!isIdentical)
        {
            throw new WcfWriteArgumentException();
        }
    }

    return returnValue;
}
Deciding what to proxy
So far this implementation intercepts every WCF call – which is heavier than we want. Being able to declare, per endpoint, exactly which service methods to intercept makes the whole thing opt-in and low-risk.
Two attributes allow exactly that:
public class ProxyReadsForAttribute : ProxyAttributeBase { ... }
public class ProxyWritesForAttribute : ProxyAttributeBase { ... }

public class MyController : Controller
{
    [ProxyReadsFor(typeof(IChannelToProxy), "MyMethod")]
    [ProxyWritesFor(typeof(IChannelToProxy), "MyMethod")]
    public ActionResult EndpointMethod()
    {
        // ...
    }
}
A ProxyAttributeScanner reflects over all controllers in the assembly at startup, collecting declared attributes into a TypeProxyRegistry. Registered through a DI module at application start-up, the registry lets the ChannelFactory decide – per type – whether to wrap the Channel in a Scientist proxy or fall back to the legacy implementation. Everything not explicitly opted in continues along the existing code path untouched.
Diffing responses
For comparing the HTTP responses themselves, Scientist exposes a Compare() hook:
return Scientist.Science<ActionResult>("experiment-key", e =>
{
    e.Use(() => GetResponseOld(someValue, ...));
    e.Try(() => GetResponseNew(someValue, ...));

    e.Compare(_resultComparer.AreSame);
});
Different controllers return different result types (ApiHttpResult, JsonResult) - but they all eventually serialise to JSON. So a comparer for each type can normalise both sides through an identical serialisation process and then diff the JSON using JsonDiffPatch, which produces a JSON PATCH describing any differences:
protected string CompareJsonData(object firstResultData, object secondResultData, bool useCamelCase)
{
    string firstResultString = _modelJsonSerialiser.SerialiseResult(firstResultData, useCamelCase);
    string secondResultString = _modelJsonSerialiser.SerialiseResult(secondResultData, useCamelCase);

    var jsonDiffPatch = new JsonDiffPatch();

    JToken firstResultToken = JToken.Parse(firstResultString);
    JToken secondResultToken = JToken.Parse(secondResultString);

    JToken diff = jsonDiffPatch.Diff(firstResultToken, secondResultToken);

    return diff?.ToString(Formatting.Indented);
}
Crucially, the serialisation settings must mirror what each result type does when it actually writes the response – same contract resolver, same Guid converter - otherwise you’ll chase phantom diffs forever.
Publishing results
Scientist’s IResultPublisher interface is the hook for surfacing mismatches. A simple LogResultPublisher implementation writes the experiment name, matched/mismatched status, control and candidate values, and durations to whichever logging pipeline the application uses (structured logging or a log aggregation platform – whatever’s already in place).
Because each result type needs slightly different formatting before logging, an IValueFormatter abstraction (CanFormat / GetFormattedValue) per result type keeps the publisher clean – with a final fallback to ToString().
For local development, MethodArgumentComparer can be configured to throw a MethodArgumentMismatchException on mismatched write arguments rather than just logging - failing fast and loudly on your machine rather than in production.
Scoping matters
HTTP is stateless, but web servers are not. Global statics and incorrectly scoped DI bindings can leak state between requests – and a method result cache is exactly the kind of stateful component that could let one user see another user’s data. (Yes, that kind of bug really happens – I’ve seen the post-mortems)
Every component needs deliberate scoping:
| Component | Stateful? | Scope | Why |
|---|---|---|---|
ProxyAttributeScanner | No | Singleton | Runs once at startup to read declared attributes |
TypeProxyRegistry | No | Singleton | Holds global registration state for all requests |
MethodArgumentComparer | No | Singleton | Stateless comparison via CompareNETObjects |
| Result comparers/formatters | No | Singleton | Stateless |
WcfMethodResultCache | Yes | Transient | Per-request storage of method results - must not leak across requests |
Take it from someone who had to revisit the Ninject bindings: get this right early.
The DateTime gotcha
One edge case that bit during rollout: fields set to DateTime.Now inside a mapping. Each code path executes at a slightly different moment, so millisecond-level differences appeared in the diff – a false positive that drowns out real signals.
The fix was to allow the comparison to ignore specific JSON property paths:
bool AreSame(T firstResult, T secondResult, string[] ignoredProperties);Before diffing, the ignored properties are pruned from both tokens, so timestamps (and any other knowingly-nondeterministic values) can be excluded per experiment:
.Compare((firstResult, secondResult) =>
    _jsonResultComparer.Compare(firstResult, secondResult,
        new[] { "lastLoginDate" }))
Any field populated with DateTime.Now - or anything derived from ambient state, randomness, or ordering - needs thinking about up front.
Feature flag everything
The final piece: the ability to revert instantly. Three flags per concern:
- Enable the refactored endpoint (canary the new code path)
- Run Scientist alongside it (compare old and new)
- A global kill-switch for Scientist itself
A controller endpoint ends up looking like:
public ActionResult EndpointMethod(string someValue)
{
    bool isScientistEnabled = _featureFlagService.IsEnabled(GlobalFeatureFlags.EnableScientist);
    bool useRefactored = _featureFlagService.IsEnabled(GlobalFeatureFlags.UseRefactoredEndpoint);
    bool useScientist = _featureFlagService.IsEnabled(GlobalFeatureFlags.UseRefactoredEndpointScientist);

    if (isScientistEnabled && useRefactored && useScientist)
    {
        return Scientist.Science<ActionResult>("experiment-key", e =>
        {
            e.Use(() => GetResponseOld(someValue, ...));
            e.Try(() => GetResponseNew(someValue, ...));

            e.Compare(_apiHttpResultComparer.AreSame);
        });
    }

    if (useRefactored)
    {
        return GetResponseNew(someValue, ...);
    }

    return GetResponseOld(someValue, ...);
}
One subtlety: TypeProxyRegistry is populated at application start-up, so gating the DI module registration behind a flag is too late – the dependency graph already exists and the ChannelFactory has already been rebound.
Instead, the registry consults the global flag inside IsTypeRegistered(), returning false for everything when the switch is off – effectively short-circuiting back to the legacy implementation without touching the container.
What about REST?
This approach covered WCF service calls. Internal REST calls were another matter – they flowed through a helper class using WebRequest.Create(), which is static, and therefore impossible to proxy with Castle.DynamicProxy.
An attempt was made. It never worked properly. The WCF implementation took about two weeks; roughly a week went into trying to get the REST side working before the effort was parked. In the interest of time, REST-backed endpoints were compared manually with KDiff instead.
Sometimes knowing when to stop is the harder engineering decision.
Retrospective
A few things I’d carry forward from this exercise:
- Runtime interception is an underused superpower in .NET. Wrapping existing implementations without touching compiled code opens doors that refactoring plans often assume are closed.
- Double-execution is expensive and sometimes dangerous. Caching results for the second path and comparing write arguments rather than re-executing avoids duplicated side effects – but it changes the semantics of the experiment, and that trade-off deserves explicit thought.
- Opt-in beats blanket interception. Attributes declaring exactly what to proxy kept the blast radius small and made removal mechanical.
- Per-request state is a landmine. Method result caches must live and die with the request.
- Determinism will lie to you.
DateTime.Nowin a mapper created endless false positives until ignored-property support landed. - Kill switches are table stakes. Layered feature flags meant every stage - refactor on, experiment on, everything on - was independently reversible.
Running controlled experiments against production traffic to validate a refactor, rather than hoping the tests cover enough, fundamentally changed how I think about modernising legacy systems safely.